
This is a summary of a longer report on our website.
AIs continue to saturate new benchmarks year after year. Yet even as the list of benchmarks where AI has surpassed humans keeps growing, the actual economic impact of AI seems to be growing more slowly.
This “productivity paradox” reflects several facts about benchmarks: they are often calibrated to measure cutting-edge AI progress compared to past capabilities (rather than against human performance); they are often limited to tasks where performance can be easily graded; and AIs are sometimes trained to the benchmark, like a high school student being taught to the SAT. All of these create a gap between how an AI scores on benchmarks and what it can actually do in the real world.
To better understand how close AI is to doing real human jobs, we need ways to close that gap.
Last February, Epoch senior researcher Anson Ho attempted to automate away his job, testing where AI could handle his tasks — and where it fell short. The answer: It failed all of the tasks, but he forecast that wouldn’t be the case by the end of the decade.
Recently, we expanded that initial effort into the Epoch Automation Reports, a collection of tasks we do regularly at Epoch, such as graphic design and planning research projects, on which we evaluate AI according to the same standards we expect of human work.
Evaluating AI on these tasks is more work than most standard benchmarks, but better represents the challenges of real work: They require models to gather context, use tools, and handle the complexity that Epoch’s human workers face.
So, how did the models do?
The leaders, Claude Fable 5.1 and GPT-6 Astra, scored 65% on average. That means their output met 65% of the rubric items that human employees would be evaluated on — a score of 100% would mean that it’s fine to automate the task.
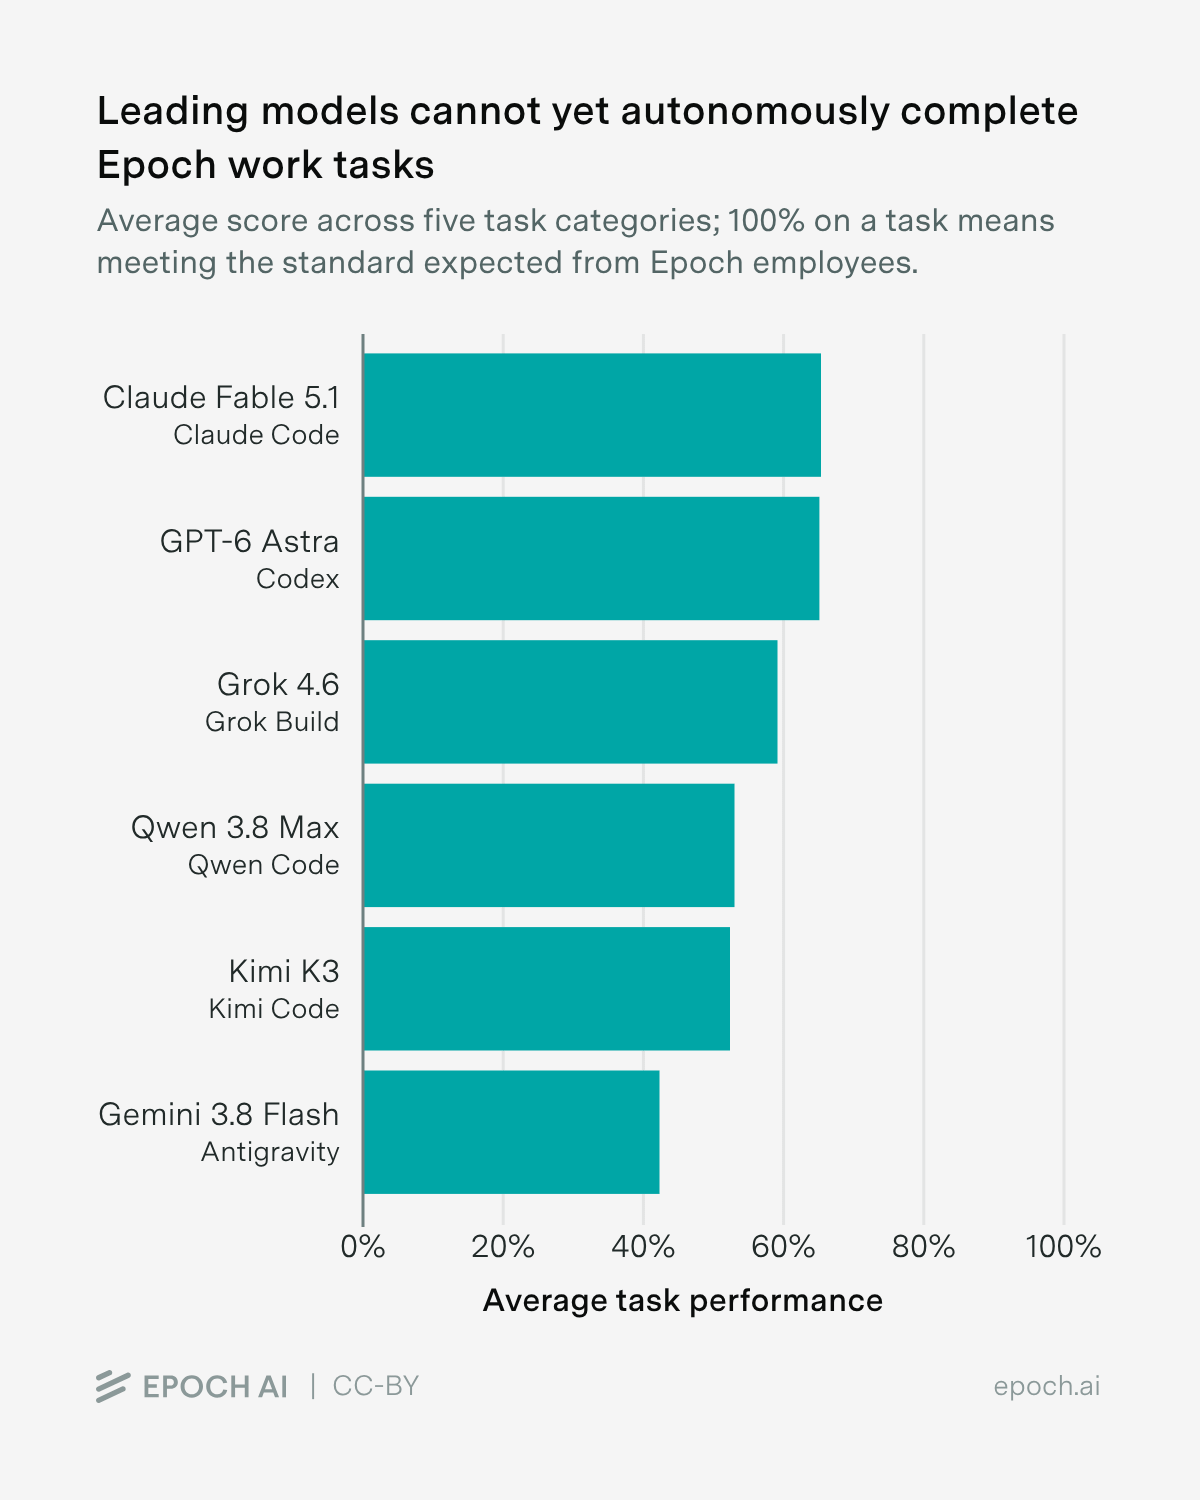
A 65% score is still a failed task
These results don’t necessarily mean we’re 65% of the way towards automation in terms of time or task difficulty, even though leading AIs can achieve 65% of the quality required from a human Epoch employee.
For starters, these scores might reflect success on easier rubric items. For example, AIs can generate promising research directions, but struggle on the harder task of creating actionable experiments. When carrying out a pilot experiment, GPT-6 Astra set the token budget too low for the models it was evaluating, so that 22% of runs were unable to return any answer. But it then treated these failures as a key finding about model capabilities, rather than a setup flaw.
In general, the AIs did better at clearly defined tasks (e.g. coding and data analysis), and worse at open-ended ones (e.g. picking up patterns from examples and tasks that involve judgment). When asked to design a graphic and provided many examples of Epoch’s style, Fable 5.1 produced a cluttered graph crammed with too much information to communicate effectively. In contrast, an Epoch designer given the task provided a clean, simple chart.
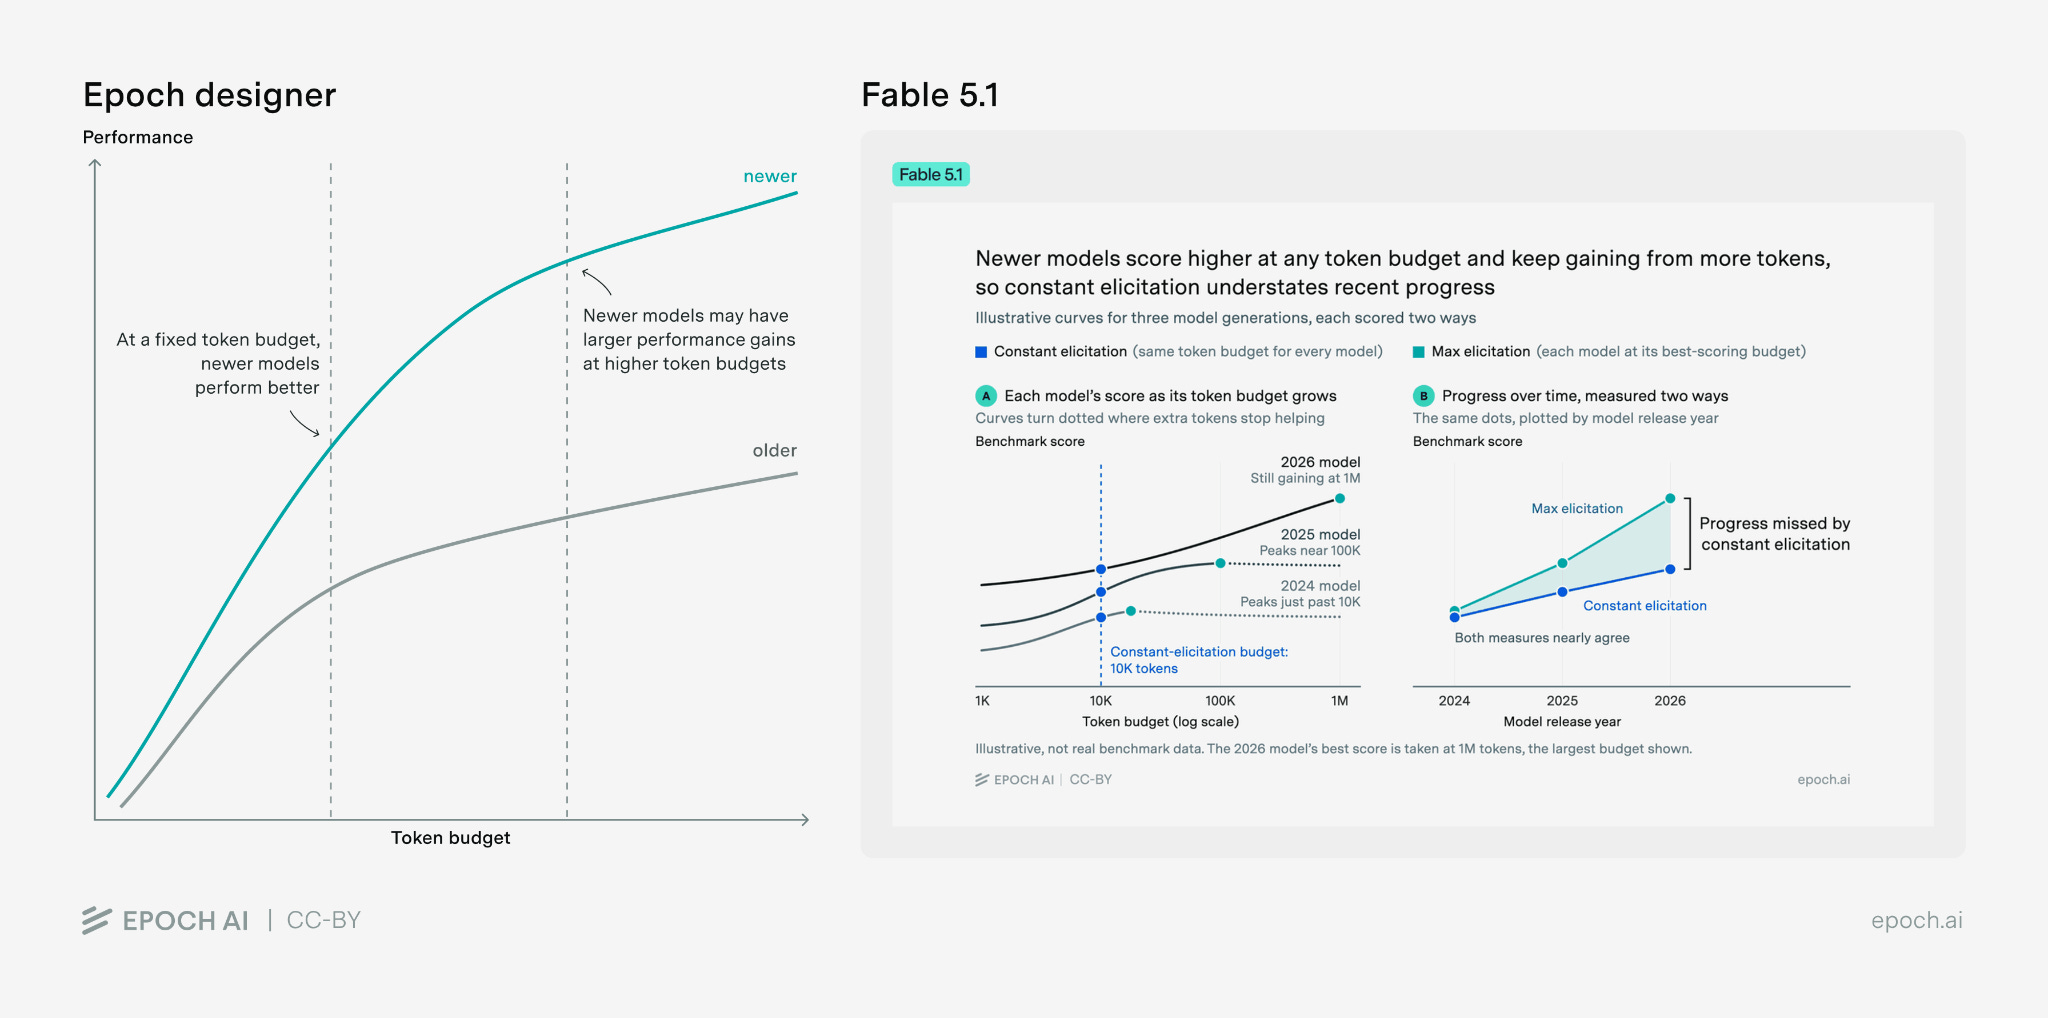
These findings give a possible explanation for why economic impact lags — 65% isn’t sufficient. Every one of those tasks would be rejected or revised if a human had submitted it. While such outputs can be helpful, they still require a human to evaluate and fix each mistake. But as AI continues to get better, it will tip over the 100% threshold for more tasks, and then the humans will hand that task over to the AI.
This has already happened with one task in this evaluation. We removed a basic chart-generation task because Fable 5.1 is able to produce an acceptable chart in one try most of the time. Epoch now partly automates this step in our daily work. As AI hits human-quality thresholds for more tasks, we expect to see a lot more economic impact.
Your 65%-of-rubric finding has a starker counterpart in paid work: on the Remote Labor Index, 240 real freelance projects across 23 domains, the best-performing agent achieved 2.5% automation and GPT-5 managed 1.7%, while the same model scores 57-58% on a ten-domain cognitive battery. The failure distribution rhymes with yours, since 45.6% of freelance failures were work below professional standard and another 35.7% incomplete or malformed deliverables, the same open-ended-judgment gap that had GPT-6 Astra reading its own token-budget flaw as a finding about the models. Both point the same direction: readiness tracks the floor, and coherence-weighted scoring that penalizes jagged profiles drops GPT-5 from 57% to roughly 24%. https://seldondance.substack.com/p/agi-heading-into-2026 #AIEvaluation #AGI
> he forecast that wouldn’t be the case by the end of the decade.
Is that from extrapolating (Epoch tasks success %, release date) data points, or from external info/data?